PostgreSQL uses Multi-Version Concurrency Control (MVCC) to manage concurrent access to the database, and store each version of a tuple in a table. To keep the database efficient, PostgreSQL employs a cleanup process called VACUUM, which removes unnecessary tuples. This not only saves disk space and keeps the database size under control, it also prevents the dreaded “Transaction ID Wraparound” issue. Regularly running VACUUM is crucial, including on the template0 database, which is normally handled by the Autovacuum daemon. However, sometimes manual intervention is necessary.

Let me preface this blog posting with a warning. Actually, two warnings:
Ensure your PostgreSQL database server never reaches the point where this step is necessary. It’s just too much trouble, and no one likes a service downtime, least your customers. Good monitoring and proactive maintenance will avoid this trouble, keep your customers happy.
That said, the step of manually running VACUUM in the
template0database requires updating the catalog. Be extra careful when changing the catalog, a wrong update risks loosing or damaging data!
What is Multi-Version Concurrency Control (MVCC)?
MVCC in PostgreSQL involves storing each version of a tuple in the same table. This mechanism is supported by additional system columns in every table. VACUUM works by examining these tuples and deciding, based on the oldest ongoing transaction, which tuples are still needed. Dead tuples are removed, and space is reclaimed for future operations. Long-lived tuples are “frozen” to mark them as always visible.
The details about additional system columns in tables are explained in my ctid and other PostgreSQL table internals blog posting.
Understanding Transaction ID Wraparound
PostgreSQL manages transaction IDs using a 32-bit integer, creating a range of 2^32 (4,294,967,296) transactions. The range is split in half, with 2^31 (2,147,483,648) transactions in the past being visible, and the same number in the future being invisible. If VACUUM doesn’t process tables in time, the database will wrap around and very old data can become invisible, leading to potential data loss.
Example
| |
The current transaction is:
| |
Assume the current transaction ID is 110,753. The visible range is from -2,147,372,895 to 110,753.
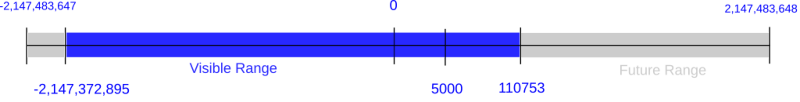
Transaction ID Wraparound: data becomes invisible
Let’s keep the database running for a while, and the Transaction ID moves forward. At one point it wrapped over and it’s -2,147,375,895 now.
The visible range for the data is 107753 to -2,147,375,895 (including the overrun at 2,147,483,648), and the future (invisible) range is -2,147,375,894 to 107752.
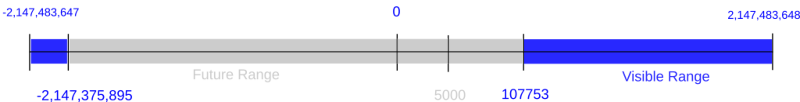
Note that the tuple with xmin=5000 is squarely within the “future range”, and therefore invisible for any queries. That’s not what we want! Not at all!
In order to avoid this data loss scenario, VACUUM will eventually mark this row as frozen. This requires that VACUUM must check every table and database before the Transaction ID wraraound occurs, so once every less than 2^31 transactions.
PostgreSQL has a number of safeguards in place to ensure that such a wraparound and data loss does not happen.
The autovacuum_freeze_max_age setting (default: 200 million transactions) lets the Autovacuum daemon start freezing tables which have rows that old.
If that does not work, or doesn’t handle tables fast enough, the vacuum_failsafe_age (default: 1.6 billion transactions) enables very aggressive vacuum on tables. No more delays, it even starts a VACUUM even if Autovacuum is disabled. Unfortunately this might happen during business hours, and will slow down your production system. But still better than a service outage.
And if that doesn’t enough, the database starts emitting warnings in the logfile:
| |
Your monitoring is supposed to pick this up and raise an alert! If everything fails, and PostgreSQL is about to wrap around the transaction id counter, the service will shutdown and you have to manually start the server in single-user mode and run VACUUM.
How to fix the wraparound problem: run VACUUM
While Autovacuum is still running in another database, and we can’t really force it to look at the next database, we can however manually complete the necessary freeze in all other databases.
The way to do this is to run VACUUM FREEZE in every database and on every object (table, index).
Note that you need to be a superuser in order to run VACUUM. While the database owner can run VACUUM on all objects in the database, this does not apply to shared objects (like the pg_database table). Only a superuser can freeze such tables.
Let’s say we have a scenario where the database hasn’t seen a VACUUM for a very long time:
| |
Here we have three databases, all three close to the wraparound. A common scenario for this to happen is that Autovacuum is busy working on one very large database, and never completes this task. All other databases get neglected. It is easy to fix two of the issues right away:
| |
| |
With that, two-third of the problems are gone:
| |
VACUUM template0
This approach does not work for the template0 database:
| |
Connections to template0 are forbidden by default. This database is empty, and VACUUM really only needs to peek into it, and then mark this database as frozen. Let’s “unlock” it:
| |
Note: the next step is updating the catalog, be careful what you are doing!
| |
Now connect to template0 and run VACUUM:
| |
That worked. Let’s make sure to lock the database again:
| |
| |
And verify the transaction age:
| |
Crisis averted!
Summary
This article shows what MVCC is, how PostgreSQL stores different versions of data tuples, and how VACUUM removes dead tuples.
And in case of Autovacuum not being able to keep up with the changes, this article shows how to manually run a VACUUM in all databases, including template0.
Image
Header image based on an image by Michal Jarmoluk from Pixabay. Modifications by me.
Comments
With an account on the Fediverse or Mastodon, you can respond to this post. Known replies are displayed below:
Note: This will load data from mastodon.social.
Learn how this is implemented here.
Share: